 NEURAL APPS
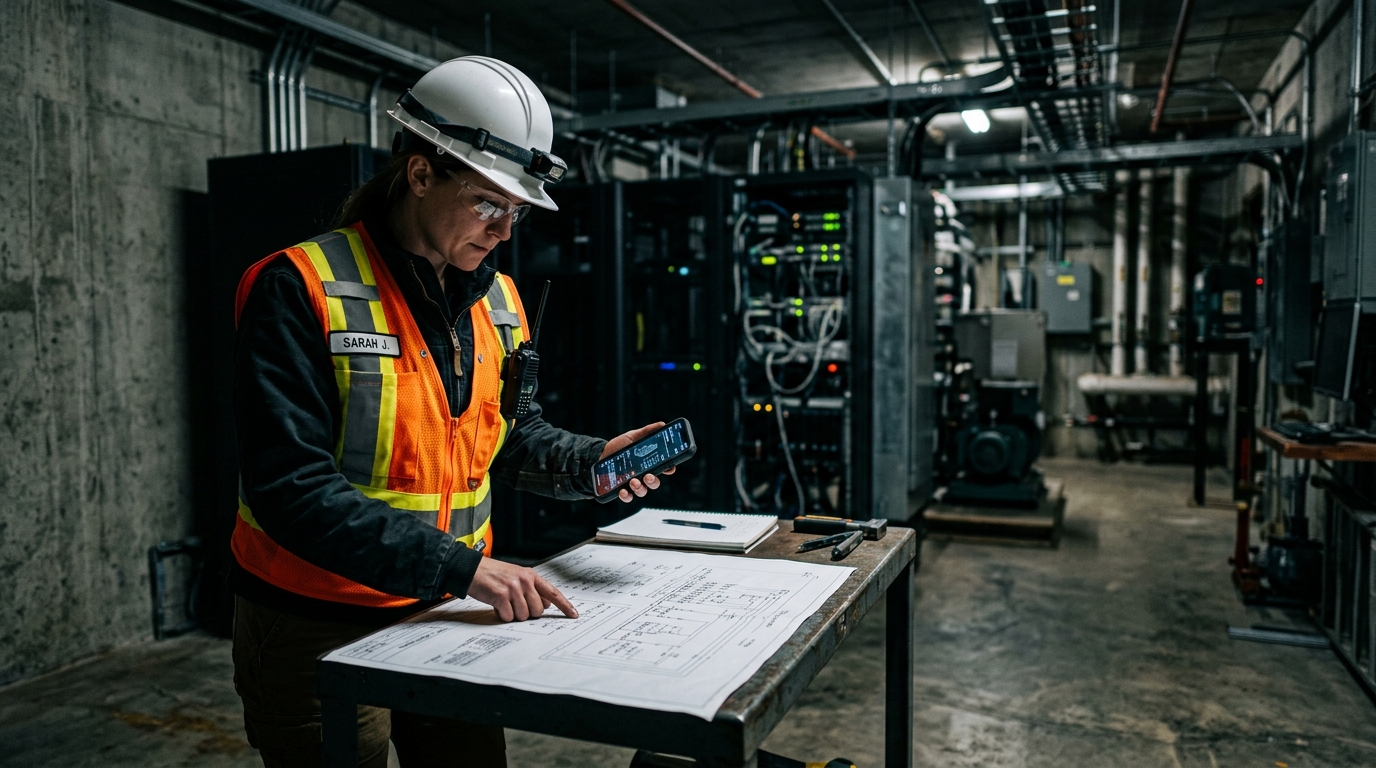
Consider a field engineer standing in the concrete sub-basement of a commercial manufacturing facility, entirely cut off from cellular and wireless networks. She needs to extract specific electrical safety clauses from a dense, 500-page schematic manual using a mobile pdf editor, execute a complex diagnostic routine, and log the preliminary compliance data into the enterprise CRM system. She is equipped with a company-issued iPhone 11. Three floors above her, the site manager is monitoring incoming data streams on an iPhone 14 Pro, waiting for the system to synchronize. This environment represents the true operational test for modern artificial intelligence. It is not about what algorithms can achieve in pristine laboratory conditions; it is about what they can execute in the harsh, disconnected realities of daily commerce.
Edge-enabled enterprise AI means running a supported part of a workload locally. Offline completion still depends on the model, files, licenses, permissions, and synchronization requirements being available on the device. This guide describes an evaluation approach, without claiming uninterrupted operation or an independently verified author tenure.
Hardware fragmentation creates the ultimate deployment test
One of the most persistent realities in enterprise technology is the mixed-hardware fleet. Organizations rarely upgrade every device simultaneously. A corporate ecosystem might easily contain entry-level legacy devices, mid-tier workhorses, and premium flagships all operating simultaneously. Building software that assumes maximum hardware capacity is a guaranteed path to operational failure.
Devices vary in available memory, processor capability, thermal limits, and background-execution constraints. Set the model and task budget using recorded tests on the supported hardware. Where the workload is too demanding, provide a smaller model, a server-assisted option, or a clear unsupported-task message; do not infer battery life or processing capacity from the device name alone.
The required workflow may be the same across devices, while the available compute and memory differ. Test which steps remain available when a connection is lost, how incomplete work is saved, and what the user sees while server-dependent steps wait. Local execution alone is not proof of reliable offline completion.
Organizations are constructing localized processing ecosystems
The industry is moving away from the assumption that all artificial intelligence must live in distant, centralized server farms. The logistical and financial overhead of transmitting every piece of enterprise data back and forth to a server is becoming unsustainable, especially as data volume multiplies. We are seeing a fundamental restructuring of how companies approach infrastructure.
Here, an AI factory is a reusable development pipeline for models, test data, deployment, and monitoring. It is a planning concept for this article, rather than a verified market trend or a claim that a complete NeuralApps fleet deployment has been measured.
Evaluate local and hosted processing using the actual workload, support burden, data requirements, and total operating cost. Unsupported market-size figures do not establish that all enterprises want the same deployment model.
Task-specific agents outmaneuver generalized systems
Building an AI factory requires making strict decisions about what models are actually necessary. Pushing a massive, generalized language model onto a phone is highly inefficient. Generalized models carry immense computational weight because they are trained to answer questions about everything from quantum physics to ancient history. A field technician does not need their device to write poetry; they need it to accurately categorize a maintenance record.
A focused model may suit a narrow extraction or classification task, but its size and background resource use still need measurement. LiteRT's benchmarking documentation explains measurements such as initialization, inference time, and memory use. Core ML documentation is an iOS deployment reference; neither source proves a particular NeuralApps app's battery or offline behavior.
When you combine these small models, you create a complex, responsive environment. One agent might handle optical character recognition for document scanning, while another routes the extracted data into the appropriate database fields. My colleague Umut Bayrak covered this topic in detail, exploring the technical mechanics of integrating efficient neural networks and localized agents into mobile hardware architectures. The goal is always to reduce the distance between the user's intent and the completed action.
A sustainable infrastructure requires strict product discipline
Transitioning from a traditional cloud-reliant architecture to an edge-first AI factory requires rigorous discipline in development. Every feature must justify its computational cost. It is easy to build applications that look impressive in a boardroom demonstration, but evaluating software requires looking at how it performs during a frantic, high-pressure shift on a rainy Tuesday afternoon.
When selecting or developing these platforms, technology leaders should apply a strict evaluation framework. First, determine the offline capability: what exact percentage of the application's core value proposition functions without an internet connection? Second, evaluate hardware elasticity: does the application gracefully degrade its processing intensity on older devices while maximizing the neural capacity of newer ones? Finally, assess workflow integration: does the intelligence naturally sit within the user's existing path, or does it require them to abandon their current screen to interact with a separate conversational interface?
As a software development firm specializing in these architectures, our philosophy at NeuralApps is rooted in this practical reality. We believe that innovative digital experiences are not defined by how complex their underlying algorithms are, but by how quietly they solve the user's problem. When we build systems that respect hardware limits, minimize cloud dependencies, and prioritize localized execution, we deliver software that actually works when it matters most.